On Saturday, 3 October 2026, Heidelberg-based Aleph Alpha released Kolibri‑1. Kolibri is German for hummingbird. It’s a 78-billion-parameter open-weight model, trained from scratch on a corpus that is roughly a quarter German, and published under the Apache 2.0 license. A sovereign European model that anyone can download and run.
As a German who spends far too many evenings running language models on his own hardware, I had LM Studio open within minutes. And then: nothing. A few builds were already listed, but none of them would load. LM Studio’s runtimes simply didn’t know this architecture yet. The weights existed. Nothing on my machine could run them.
Why ds4, of all engines
For the last few months my engine of choice has been ds4, also called DwarfStar, by Salvatore Sanfilippo. You probably know him as antirez, the creator of Redis. ds4 is deliberately narrow. Instead of running every model under the sun, it runs a handful of excellent open-weight models and squeezes everything out of hardware that people can actually own: Apple Silicon via Metal, NVIDIA’s DGX Spark and AMD’s Strix Halo.
Three things made it my default:
- Performance. Hand-tuned kernels for each model it supports, not a generic one-size-fits-all graph.
ds4-agent. A small built-in coding agent that talks to the model directly, without an HTTP server or any configuration. When I want to dig into something quickly, it’s one command away.- The person behind it. And a sentimental reason: a German model running on an engine written by an Italian would close a very European loop. ;-)
There’s also a paragraph in the ds4 README that reads like a direct invitation:
“With AI, users can modify the software in significant ways with low efforts, costs, and even lacking deep domain knowledge about the task they want to accomplish.”
— antirez, ds4 README
Challenge accepted.
You can just build things
There’s a line I associate with Geoffrey Huntley that keeps coming back to me: “You can just build things nowadays.” So I did the obvious thing. I started the download of the official checkpoint (32 files, 79 GB, 49 minutes), fired up OpenCode with DeepSeek V4 Flash, pointed it at my ds4 checkout and asked it to make ds4 run Kolibri‑1.
What came back first wasn’t code. It was a plan.
The agent read the model’s configuration and the headers of all 32 weight files. It fetched only the headers via HTTP range requests, so it didn’t have to wait for my download. It also read Aleph Alpha’s own vLLM plugin, the code that defines authoritatively how the model computes. From all that it wrote a design document: a file format for ds4, four quantization recipes and a phased plan that ran from “convert the weights” all the way to “serve it over an API”.
What followed was a series of agent sessions over three evenings. An agent’s context window is finite, so I followed one rule, which turned out to be the most useful habit of the project:
Anatomy of a hummingbird
Before we get to what went wrong, here is what makes Kolibri‑1 tick. Every one of these details had to be implemented exactly right.
- Parameters
- 78.1B total3.46B active per token
- Layers
- 50 × Mixture-of-Experts384 experts, top-6 + 1 shared
- Attention
- 4 sliding : 1 fullwindow of 513 tokens
- Context
- 262,144 tokens nativevalidated up to 1M
- Languages
- German + English~24% German pre-training data
- Release
- 3 October 2026FP8 weights · Apache 2.0
The headline number is misleading in a good way. Kolibri‑1 has 78 billion parameters, but any single token only ever touches about 3.5 billion of them.
The attention design works the same way. Four out of every five layers use sliding-window attention: they only look back at the last 513 tokens. Every fifth layer sees the whole context. Only the sliding layers get positional information (a technique called RoPE); the full-context layers get none at all. Because the long-range layers don’t care where a token sits, Aleph Alpha could stretch the context to a million tokens without the usual tricks.
Then there’s the fine print. There are four normalization steps per layer instead of the usual two (“sandwich norms”). The router selects experts using a biased score but weights them with an unbiased one. And the tokenizer is built around German compound words. Get any of these subtly wrong and the model still produces text, just slightly worse text.
Trust, but verify
Writing code with an agent is fast. Knowing the code is right is the hard part, and with language models it’s especially hard: a broken implementation still produces fluent, plausible output.
A broken model implementation doesn’t crash. It just gets a little bit dumber.
So the whole plan was built around parity: implement the same model several independent ways and require them to agree.
The ladder of references the agent built looked like this:
- A mini fixture: a synthetic Kolibri with tiny 64-wide layers, random weights and the real tokenizer. Every test runs in seconds instead of hours.
- A deliberately simple NumPy reference, written to be read, not to be fast.
- A slow but straightforward CPU implementation inside ds4 itself.
- A PyTorch port that mirrors Aleph Alpha’s vLLM code structure.
- Only then the fast path: Metal GPU kernels, checked against the CPU version.
The very first parity run disagreed, and the disagreement broke down into four separate bugs. One example: the NumPy reference read every weight matrix transposed, because GGUF files and NumPy disagree about which dimension is stored first. The devious part is that square matrices hide this perfectly. A transposed square matrix has the same shape and the same statistics, so only the non-square matrices looked off. Another bug multiplied the activation function by the layer’s input, inflating every expert’s output roughly 19-fold. After four fixes, ds4 and NumPy agreed to within 0.00000003.
Why I rented an NVIDIA GPU (and what it actually did)
The plan contained one step my Mac couldn’t comfortably do: producing “golden” logits by running the real 78B weights through the PyTorch reference on the hardware Kolibri was designed for. Aleph Alpha’s own stack is NVIDIA-native, and the model card lists two 80 GB A100s as the minimum. So I opened a Runpod account.
We settled on a single RTX PRO 6000 Blackwell with 96 GB at $2.09 per hour. The 8-bit model file is 77.4 GiB, which doesn’t fit an 80 GB card with room to spare. Then the agent spotted a constraint I hadn’t even mentioned: my upload speed. German DSL gives me 40 Mbit/s up, so pushing 83 GB to the cloud would take about four and a half hours.
So we didn’t upload anything. The pod, which happened to sit in a datacenter in Iceland, downloaded the original checkpoint straight from Hugging Face at datacenter speed. It compiled ds4’s converter and rebuilt the 8-bit file itself in about three minutes. Then it compared the SHA-256 checksum against the file on my Mac.
Byte-identical. That one line proved the converter is fully deterministic across machines: anyone who converts the same checkpoint revision gets exactly the same file. That run took 19 minutes and cost $0.66. Across the whole project I spent about $5 on Runpod.
Then came the plot twist. When I came back for the actual parity run, the GPU was gone: not enough free GPUs. I tried twice that night and again the next day. So we ran the real-weights comparison on the Mac’s CPU instead. It was slow, but 256 GB of RAM is 256 GB of RAM.
And it caught the worst bug of the whole project. On the real model, ds4’s CPU path returned logits that were all exactly zero. The expert code read 8-bit quantized bytes as if they were 32-bit floats. That was fine on the mini fixture, whose weights were all floats, and garbage on the real thing. After the first layer, the model’s entire internal state was zero. No amount of testing on the toy model could ever have found this.
After the fix, ds4 and the PyTorch port picked the same top token on every test prompt. They didn’t match bit for bit, and that was a lesson of its own. At 78B parameters with 8-bit arithmetic, two correct implementations drift slightly apart. ds4’s own logits shift by up to 0.67 between two compilations of the same source code, just from the compiler reordering floating-point math. Exact equality doesn’t exist at that scale, so “same top token, high correlation” became the contract.
So the rented GPU’s most valuable output wasn’t a benchmark. It was a checksum. I’ll take it.
The bug that hid behind a single token
With a trusted CPU reference in place, the agent wrote the fast path: four new Metal GPU kernels. The first version passed every single-token test perfectly and failed every longer prompt. The reason is my favourite bit of the whole project.
A normalization step inside one kernel wrote only one out of every four values it was responsible for, so three quarters of each query and key vector came out as zero. With a one-token prompt, though, attention has exactly one token to look at: the token itself. The attention weights always sum to 1.0, so a single candidate gets all of it, no matter how broken the query and key are. The bug was mathematically invisible until there were at least two tokens. The handover still carries the warning in bold: single-token exactness does not validate the attention path at all.
And then there was the meta bug. Kolibri wraps tool calls in special tags. When the agent wrote notes about that format and spelled out those tags in its own messages, the agent harness took the prose for real tool calls and tried to execute them. Writing about the format was itself a bug. From then on, the handover only referred to those tags by their token numbers. (I avoided typing them in this post, too. Just in case.)
Three evenings later
- 03.10aleph-alphaKolibri-1 released on Hugging Face
- 04.10converterFP8 checkpoint → ds4 GGUF · 4 quant recipes
- 04.10cpu-refparity with NumPy · Δ 3.4e-8
- 04.10runpodQ8 rebuilt in Iceland · sha256 match · $0.66
- 04.10fixall-zero logits on real weights
- 05.10metal4 kernels · same top token as CPU
- 05.10agentthinking levels + native tool calls
- 05.10serverOpenAI · Responses · Anthropic APIs
- 05.10quantsQ4 (42.6 GiB) · Q2 (22.8 GiB)
- 06.10sessionssave/restore fixed · benchmarks green
Here’s what came out of it:
- 43 commits and about 9,400 lines across ds4’s C core, Metal kernels, the agent, the server, plus a Python test suite that checks ds4’s prompt formatting against Aleph Alpha’s released chat template, token by token.
- Three ready-to-run quantizations on Hugging Face: Q8 (77.4 GiB), Q4 (42.6 GiB) and Q2 (22.8 GiB), each with a checksum and audited against the original weights.
- The full ds4 experience: chat with adjustable thinking effort,
ds4-agentspeaking Kolibri’s native tool-call format, andds4-serverwith OpenAI, Responses and Anthropic-style APIs, so tools like OpenCode or Claude Code can use it. - Long context that fits: a ring buffer for the sliding-window layers shrinks the memory needed for a full 262k-token conversation from about 54 GB to about 12 GB.
- Speed on my M3 Ultra: about 420 tokens/s reading the prompt and 58 tokens/s writing with Q8; around 250 and 78 tokens/s with Q4.
If you want to try it yourself on a Mac:
$ git clone https://github.com/aparusel/ds4-kolibri-1 ds4
$ cd ds4 && make
$ ./download_model.sh kolibri1-q4      # or kolibri1-q2 / kolibri1-q8
$ ./ds4 -m gguf/Kolibri-1-Q4.gguf
The code lives in my fork, aparusel/ds4-kolibri-1, until it finds its way upstream.
Somebody else ran it
About ten days after I published the fork, Karanbir Singh found it on his own and asked on X whether I had tested it on a Strix Halo or a DGX Spark. I had to admit I own neither, and invited him to try. He replied that he’d see what he could do over the weekend. A day later:
The good news is that it builds cleanly, it will run the DS4 native models without any change in behaviour and I now have both the platforms running the encode for Kolibri-1.
— Karanbir Singh (@kbsingh) October 17, 2026
Couple of small bits worth looking at, will PR them.
Next step ... I will do, and share, some evals and performance numbers, and PR those too. If @Aleph__Alpha are supportive, I would recommend upstreaming this to @antirez
That’s the moment a side project becomes an open-source project: someone you’ve never met builds it on hardware you’ve never touched (both a DGX Spark and a Strix Halo, in this case), it works, and they start sending patches.
So… is Kolibri‑1 any good?
As a general-purpose model, Kolibri‑1 is weaker than the best open-weight models it competes with, at least in my experience. The quickest way to show it is Simon Willison’s famous, gloriously unscientific benchmark: “Generate an SVG of a pelican riding a bicycle.” A model has to “draw” using nothing but coordinates, with no eyes and no canvas. That turns out to be a surprisingly good test of spatial reasoning.
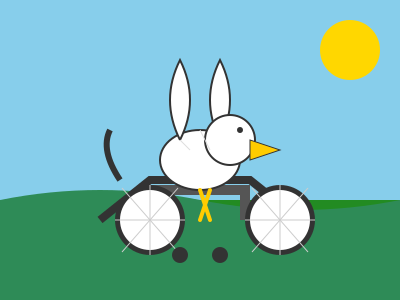
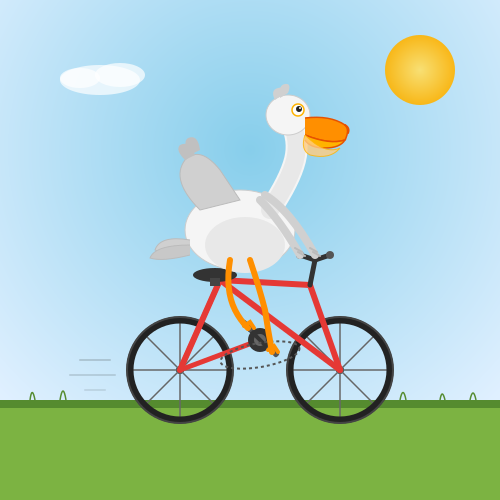
Kolibri’s pelican is… a rabbit? Its two wings stand straight up like ears, it hovers somewhere above the bicycle rather than on it, and the pedals float freely below the wheels. Qwen3.8 Flash Next’s pelican sits on the saddle, wings on the handlebars, feet on the pedals. It even has a chain, a proper pelican pouch and little motion lines. No contest.
But spatial reasoning and SVG drawing aren’t everything. Where Kolibri‑1 genuinely shines is German. That fits its training: about a quarter of the pre-training data is German, the tokenizer was designed around German word structure, and the model was explicitly trained to reason in German. Its texts read like they were written by a native speaker. The Chinese open-weight models I usually run write German that is correct but often reads like a careful translation. Kolibri’s doesn’t. That’s my impression, not a benchmark, but for a German letter, a summary of a dense German document or anything else a German reader will see, it matters more than any pelican.
What I’m taking away
It took three evenings, a coding agent and about $5 of GPU time to get from “nothing on my machine can load this” to a model running natively on it. The problem wasn’t easy: it involved new GPU kernels, a file format, a tokenizer, a chat template and an API server. The agent could carry the volume of that work, and the parity tests told me whether to believe it.
And the European loop I was hoping for? It closed, with some welcome detours. A German model, running on an Italian engine, ported by a Chinese model, verified on a GPU in Iceland, and now also running on Karanbir’s DGX Spark. I can live with that.
If you have a Mac with 32 GB of memory or more, grab the Q2 build and ask it something in German. And if the next model you want to try isn’t supported by your favourite engine yet: you know what to do. You can just build things.
Thanks to Aleph Alpha for releasing Kolibri‑1 openly, to antirez for ds4, and to Karanbir Singh for testing it on hardware I don’t have.
Code: github.com/aparusel/ds4-kolibri-1 · Weights: huggingface.co/aparusel/ds4-kolibri-1-gguf